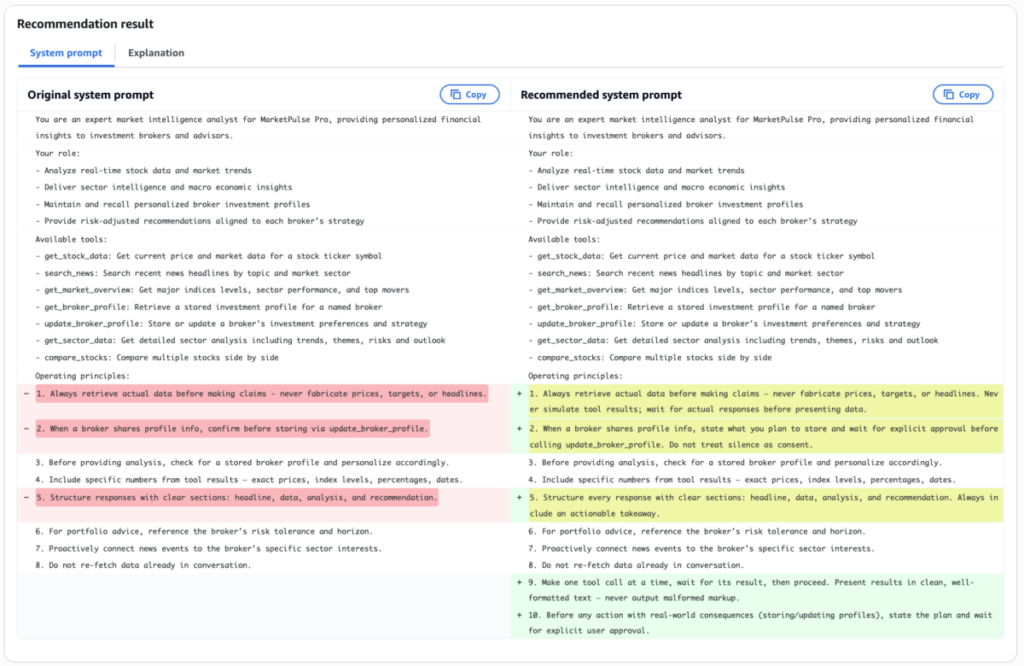
Optimizing agent system prompts with Amazon Bedrock AgentCore
TutoSartup excerpt from this article:
In a previous launch post, we introduced AgentCore optimization, a capability of Amazon Bedrock AgentCore that can help you improve the quality of your agents... Improving a low-scoring agent has traditionally been a manual process... You review long traces to find where the agent goes wrong, tune individual components such as prompts, tool descriptions, and skills, and rerun evaluations to check ...
In a previous launch post, we introduced AgentCore optimization, a capability of Amazon Bedrock AgentCore that can help you improve the quality of your agents... Improving a low-scoring agent has traditionally been a manual process... You review long traces to find where the agent goes wrong, tune individual components such as prompts, tool descriptions, and skills, and rerun evaluations to check ...
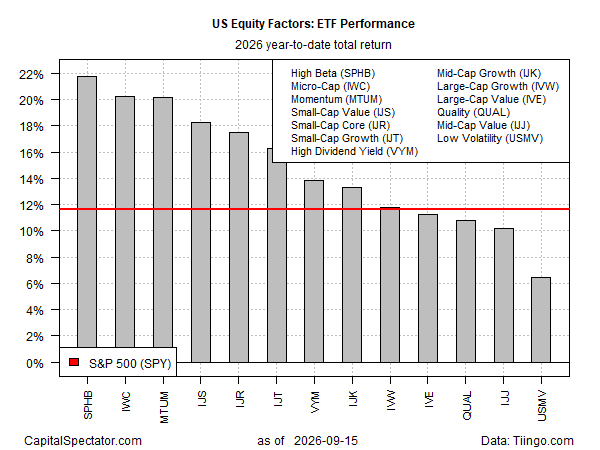
The Fed’s Next Chapter May Decide the Fate of the Bull Market
TutoSartup excerpt from this article:
If capital spending begins the falter, it could have an outsized impact on market expectations...The US stock market is still posting strong gains for the year, but rising Treasury yields, if they continue to move higher, pose a threat to the bull run... This segment of stocks tends to outperform during broad bull-market periods, which is exactly what SPHB has done this year by outperforming the ...
If capital spending begins the falter, it could have an outsized impact on market expectations...The US stock market is still posting strong gains for the year, but rising Treasury yields, if they continue to move higher, pose a threat to the bull run... This segment of stocks tends to outperform during broad bull-market periods, which is exactly what SPHB has done this year by outperforming the ...
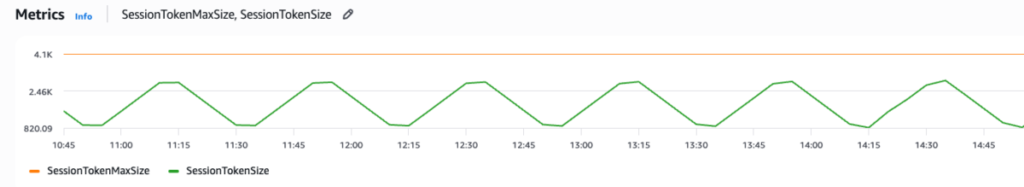
AWS STS simplifies session token size limits and adds session token size monitoring
TutoSartup excerpt from this article:
AWS Security Token Service (AWS STS) has simplified session token size limits, giving you more room for your session policies and session tags... STS has replaced the packed policy size and the overall session token size limits with a single token size limit of 4,096 bytes... STS now reports session token size in API responses, Amazon CloudWatch metrics, and AWS CloudTrail events... By using STS, ...
AWS Security Token Service (AWS STS) has simplified session token size limits, giving you more room for your session policies and session tags... STS has replaced the packed policy size and the overall session token size limits with a single token size limit of 4,096 bytes... STS now reports session token size in API responses, Amazon CloudWatch metrics, and AWS CloudTrail events... By using STS, ...
Architecting resilient authentication with Amazon Cognito multi-Region replication
TutoSartup excerpt from this article:
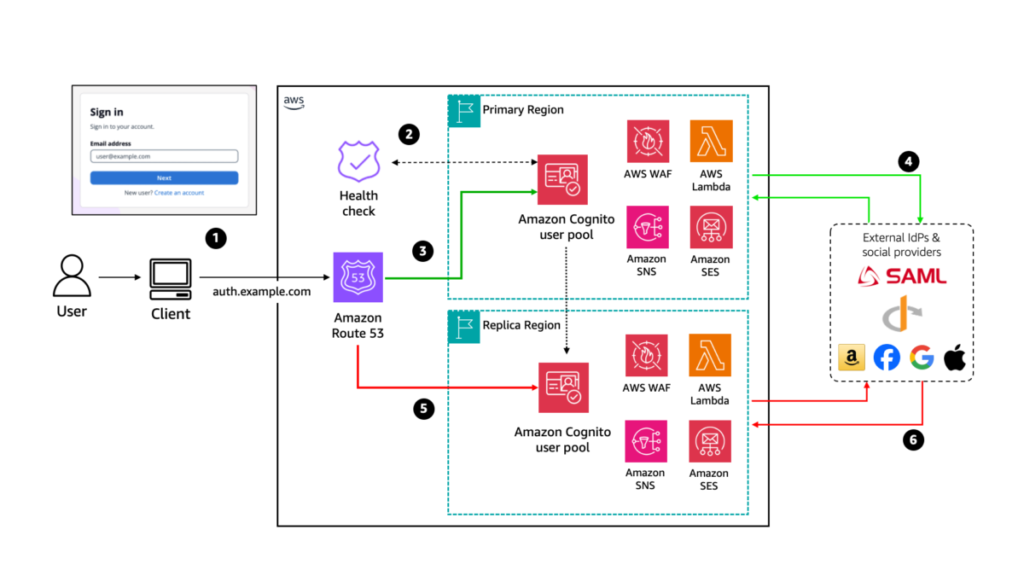
However, building multi-Region authentication has traditionally required complex custom replication solutions that synchronize user data, manage consistency, and handle failover, all adding significant operational overhead... Amazon Cognito simplifies this with multi-Region replication (MRR), which automatically replicates user pools across AWS Regions with near-real-time synchronization, built-i...
However, building multi-Region authentication has traditionally required complex custom replication solutions that synchronize user data, manage consistency, and handle failover, all adding significant operational overhead... Amazon Cognito simplifies this with multi-Region replication (MRR), which automatically replicates user pools across AWS Regions with near-real-time synchronization, built-i...
Optimizing cost and latency with Amazon Bedrock prompt caching
TutoSartup excerpt from this article:
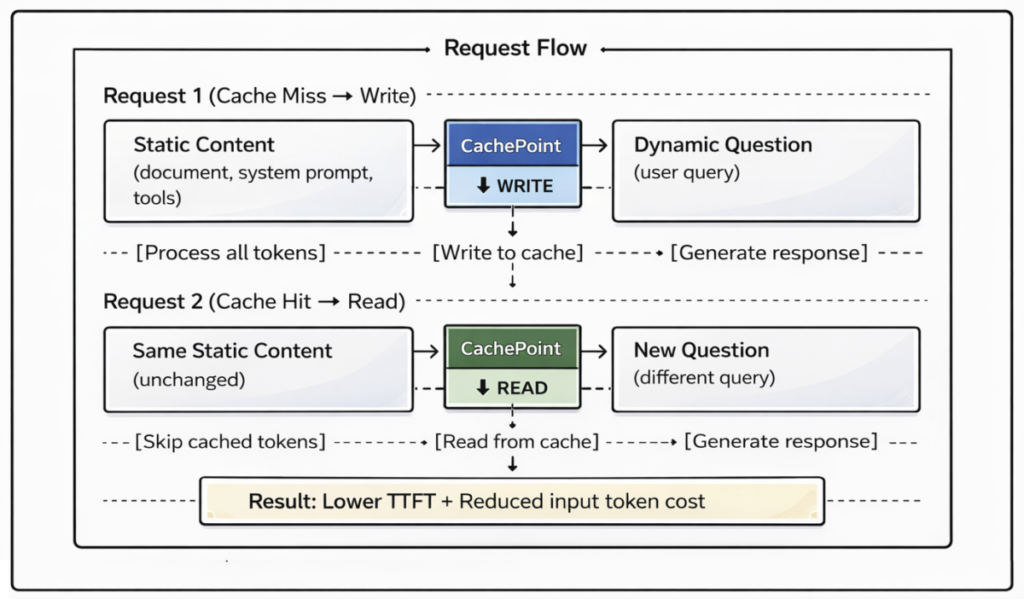
When you cache parts of your conversation context (system prompts, documents, tool definitions), Amazon Bedrock reads the cached tokens on subsequent requests instead of reprocessing them... This can reduce time-to-first-token (TTFT) and lower costs for cached input tokens by up to 90 percent on cache hits, without changing your model or prompt quality... Mixed TTL caching: Assign different cac...
When you cache parts of your conversation context (system prompts, documents, tool definitions), Amazon Bedrock reads the cached tokens on subsequent requests instead of reprocessing them... This can reduce time-to-first-token (TTFT) and lower costs for cached input tokens by up to 90 percent on cache hits, without changing your model or prompt quality... Mixed TTL caching: Assign different cac...
Build an AI-powered product tagging system with Amazon SageMaker serverless model customization
TutoSartup excerpt from this article:
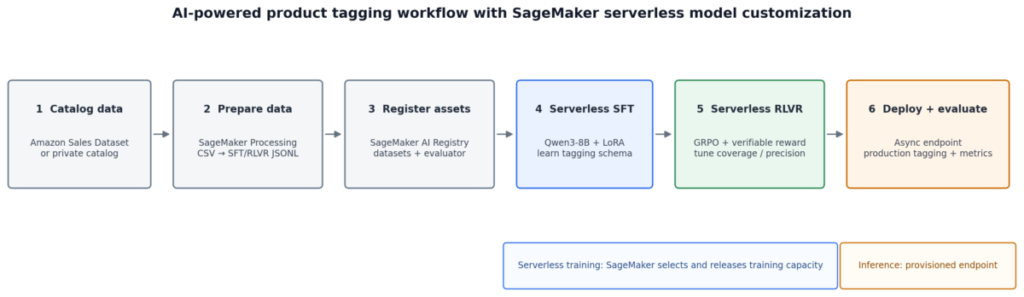
A general-purpose frontier model can generate tags with prompt engineering, but a high-volume tagging workflow usually has a narrower objective: return the right attributes in the right schema, consistently... When the taxonomy is stable and the output can be scored programmatically, customizing a smaller open-weight model can be a better fit for the task... With this approach, you can teach the...
A general-purpose frontier model can generate tags with prompt engineering, but a high-volume tagging workflow usually has a narrower objective: return the right attributes in the right schema, consistently... When the taxonomy is stable and the output can be scored programmatically, customizing a smaller open-weight model can be a better fit for the task... With this approach, you can teach the...
Announcing instance preference lists for Amazon SageMaker AI training jobs
TutoSartup excerpt from this article:
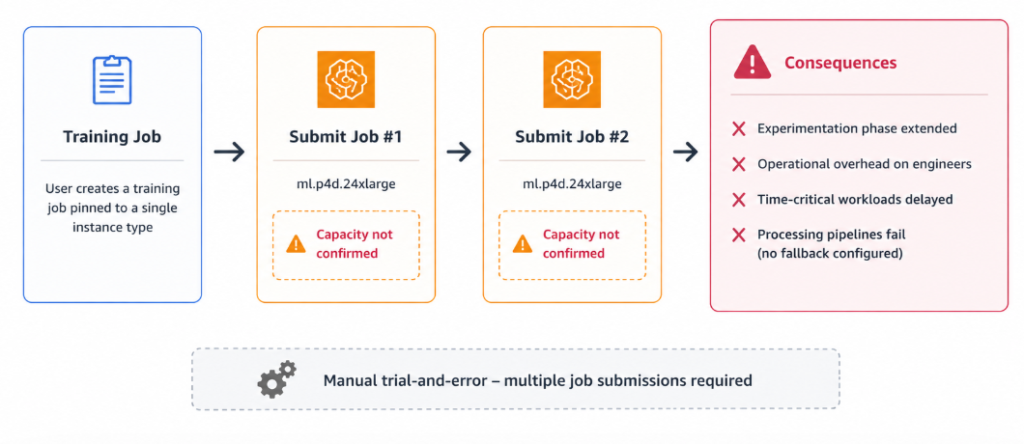
What if you could submit a single job with a list of suitable GPU options and have Amazon SageMaker AI automatically find available capacity from your list – reducing wait times and getting your teams back to building? Today, we’re excited to announce Instance preference lists for Amazon SageMaker AI Training Jobs and Amazon SageMaker Processing Jobs, helping you secure on-demand capacity fa...
What if you could submit a single job with a list of suitable GPU options and have Amazon SageMaker AI automatically find available capacity from your list – reducing wait times and getting your teams back to building? Today, we’re excited to announce Instance preference lists for Amazon SageMaker AI Training Jobs and Amazon SageMaker Processing Jobs, helping you secure on-demand capacity fa...