Four Amazon Bedrock inference choices that affect cost
TutoSartup excerpt from this article:
Cache duration, service tier, reasoning effort, and maxTokens can affect cost without changing your model or prompt... Each choice depends on the model and workload... Each sample sets its own model ID, so change it, and the inference parameters, to match the model you call... For model availability by AWS Region, refer to Models at a glance... For broader decisions such as model selection, batc...
Cache duration, service tier, reasoning effort, and maxTokens can affect cost without changing your model or prompt... Each choice depends on the model and workload... Each sample sets its own model ID, so change it, and the inference parameters, to match the model you call... For model availability by AWS Region, refer to Models at a glance... For broader decisions such as model selection, batc...
Scale distributed AI workloads with Ray and Anyscale on Amazon EC2
TutoSartup excerpt from this article:
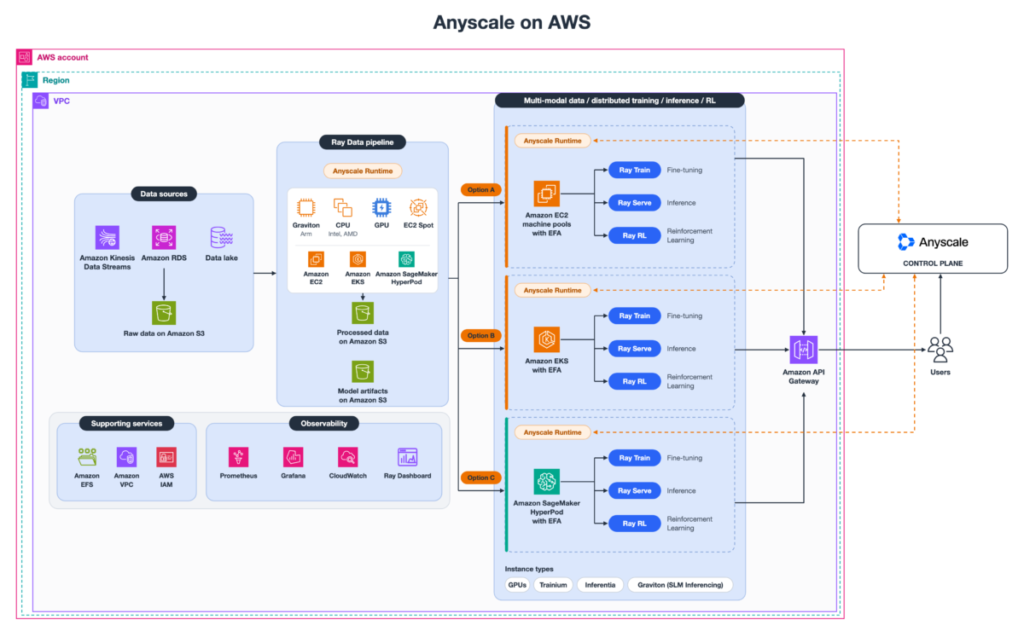
If you are building multimodal artificial intelligence and machine learning (AI/ML) pipelines on Amazon Elastic Compute Cloud (Amazon EC2) that process text, video, and audio, you have likely hit at least one of these challenges... Anyscale on AWS Many AWS customers already run self-managed Ray clusters on Amazon EC2... Anyscale builds on that foundation as a fully managed service that deploys w...
If you are building multimodal artificial intelligence and machine learning (AI/ML) pipelines on Amazon Elastic Compute Cloud (Amazon EC2) that process text, video, and audio, you have likely hit at least one of these challenges... Anyscale on AWS Many AWS customers already run self-managed Ray clusters on Amazon EC2... Anyscale builds on that foundation as a fully managed service that deploys w...
Inside an enterprise AI agent: A governed, observable loop architecture
TutoSartup excerpt from this article:
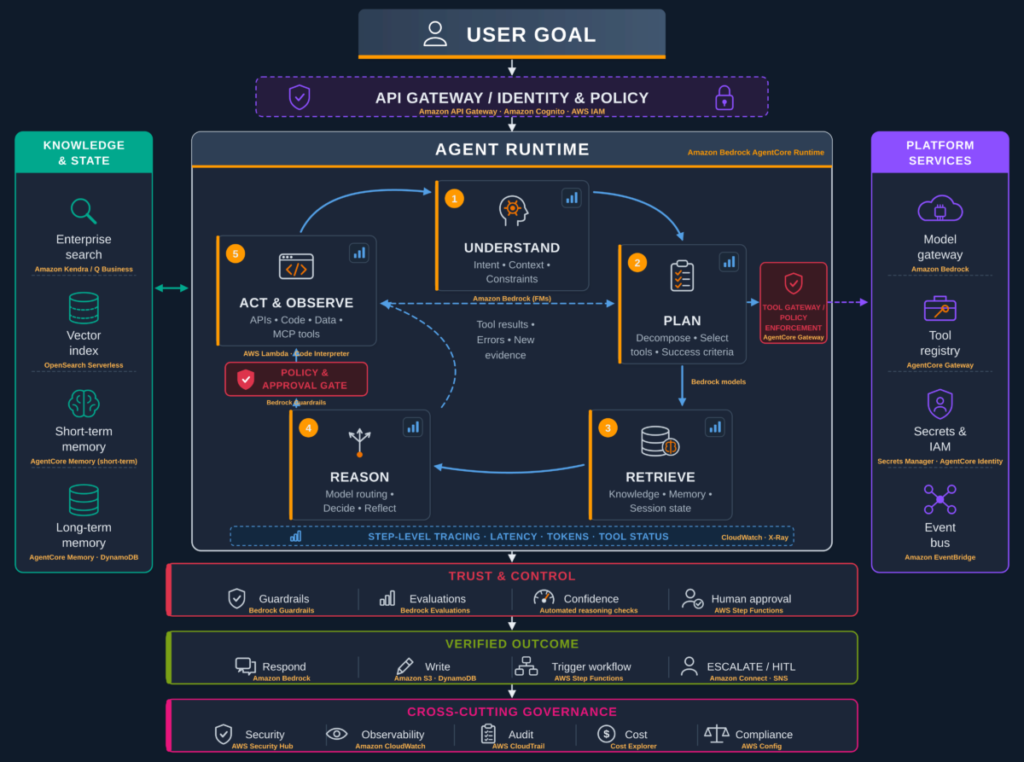
An enterprise AI agent isn’t a bigger chatbot... An agent keeps working toward a goal: it reads what the user is asking for, breaks the work into steps, pulls in the knowledge it needs, weighs the evidence, calls external tools, and checks the results before it decides whether to keep going or hand back an answer... This post lays out a reference architecture for that kind of agent, organized a...
An enterprise AI agent isn’t a bigger chatbot... An agent keeps working toward a goal: it reads what the user is asking for, breaks the work into steps, pulls in the knowledge it needs, weighs the evidence, calls external tools, and checks the results before it decides whether to keep going or hand back an answer... This post lays out a reference architecture for that kind of agent, organized a...
Tokenomics at scale: Track and cap Amazon Bedrock spend per IAM principal with CUR 2.0 and AWS Budgets
TutoSartup excerpt from this article:
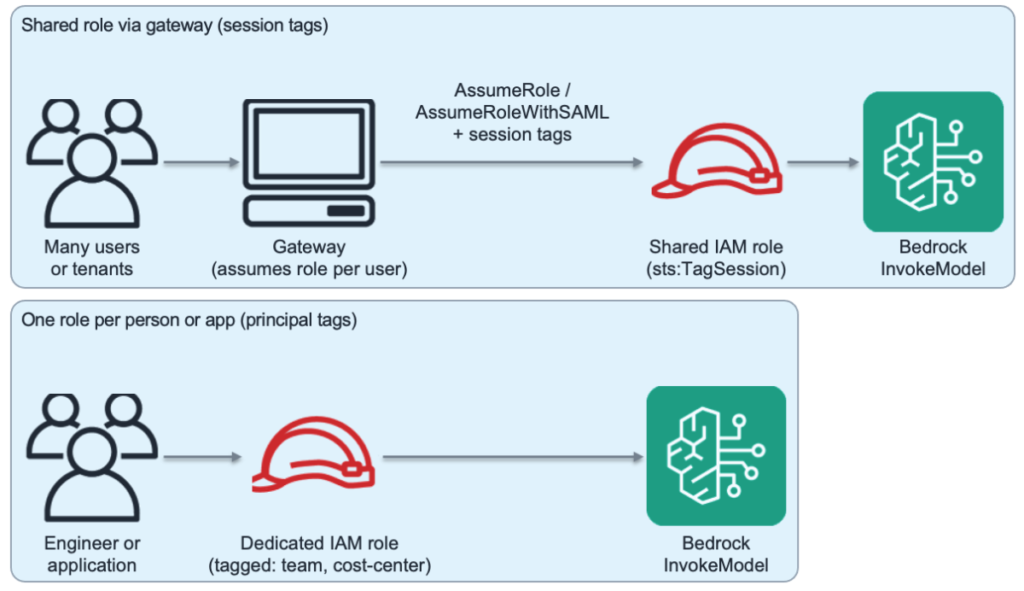
AssumeRoleWithWebIdentity, with tags in the https://aws... In our previous post, Tokenomics at Scale: How Jamf Built Real-Time Spend Enforcement for Amazon Bedrock, we explained a custom enforcement loop built on AWS IAM Identity Center, Amazon Athena over Amazon Bedrock model invocation logs, and AWS Lambda... This post shows how to get per-identity Amazon Bedrock cost visibility and enforce...
AssumeRoleWithWebIdentity, with tags in the https://aws... In our previous post, Tokenomics at Scale: How Jamf Built Real-Time Spend Enforcement for Amazon Bedrock, we explained a custom enforcement loop built on AWS IAM Identity Center, Amazon Athena over Amazon Bedrock model invocation logs, and AWS Lambda... This post shows how to get per-identity Amazon Bedrock cost visibility and enforce...
Optimizing cost per task and proving agent ROI on Amazon Bedrock
TutoSartup excerpt from this article:
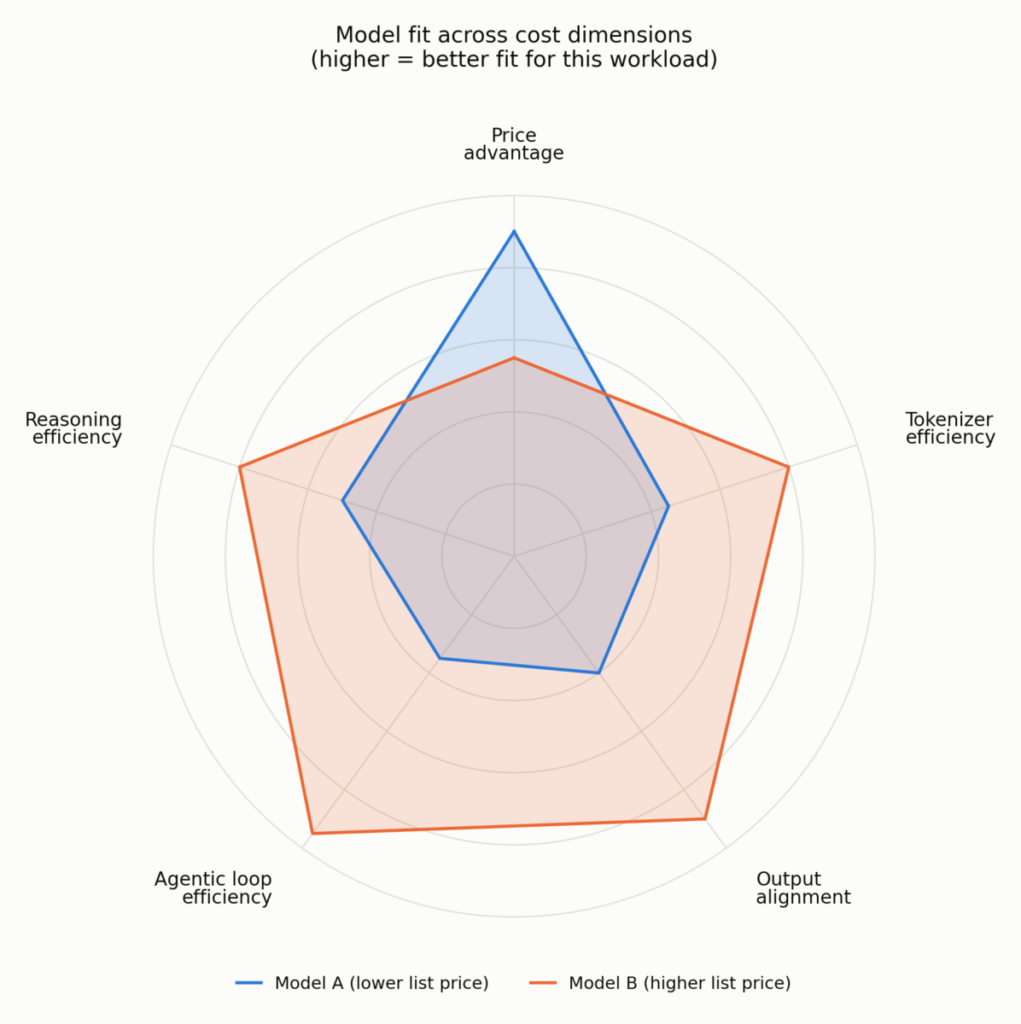
First: Why is this workflow expensive? The answer requires thinking in cost per task, not cost per token... Cost per task, not cost per token Price per token invites quick comparison, but it doesn’t reflect what you actually pay... The published rate reflects the cost of a single token... A cheaper model might fragment your text into more tokens, pad responses with filler, misread your tool s...
First: Why is this workflow expensive? The answer requires thinking in cost per task, not cost per token... Cost per task, not cost per token Price per token invites quick comparison, but it doesn’t reflect what you actually pay... The published rate reflects the cost of a single token... A cheaper model might fragment your text into more tokens, pad responses with filler, misread your tool s...
The Bond Rally Faces a Reality Check
TutoSartup excerpt from this article:
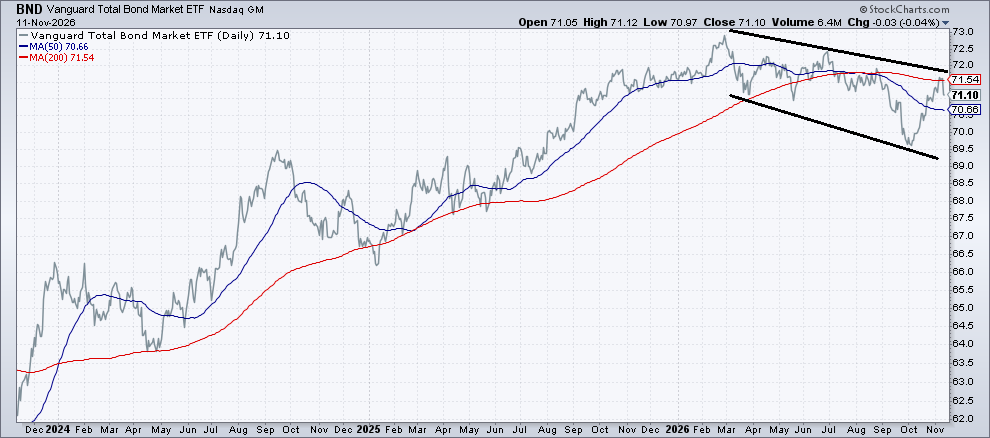
The ongoing tug-of-war between inflationary and the potential for a return of near-term disinflationary pressures could limit the bond market’s ability to establish a clear direction in the weeks ahead...October’s consumer inflation report reinforced the view that inflation remains stubborn enough to pressure bond prices and push interest rates higher...A key question for investors is...
The ongoing tug-of-war between inflationary and the potential for a return of near-term disinflationary pressures could limit the bond market’s ability to establish a clear direction in the weeks ahead...October’s consumer inflation report reinforced the view that inflation remains stubborn enough to pressure bond prices and push interest rates higher...A key question for investors is...
How Zillow runs 100 million daily notifications on AWS Step Functions
TutoSartup excerpt from this article:
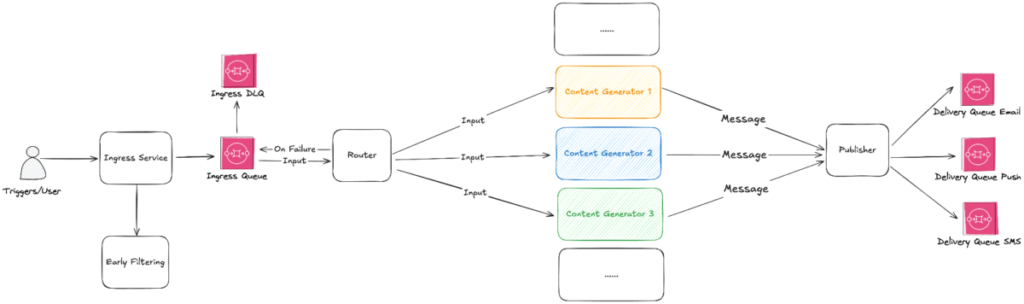
These messages are one of Zillow’s core ways to engage home shoppers, and Zillow delivers them on time with consistent behavior across every campaign... Historically at Zillow a separate generator service produced each of these campaigns, and each service carried its own workflow, data models, and business rules... As the number of notification campaigns grew, so did duplicated engineering wor...
These messages are one of Zillow’s core ways to engage home shoppers, and Zillow delivers them on time with consistent behavior across every campaign... Historically at Zillow a separate generator service produced each of these campaigns, and each service carried its own workflow, data models, and business rules... As the number of notification campaigns grew, so did duplicated engineering wor...